Patrick Will, Senior Director and Head of Software Product Marketing and Management at Infineon
iDEAL Semiconductor Announces 200 V Family of SuperQ-based MOSFETs With Industry-Leading Cost x Performance
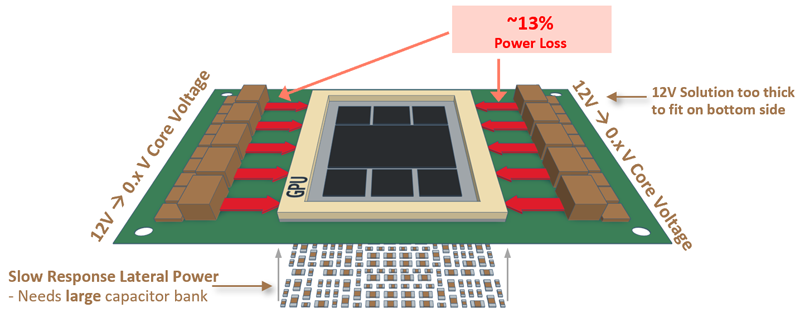
Click image to enlarge
Figure 1: LPD moves current through one layer from the board’s edge to its center
Jason Lomberg, North American Editor, PSD